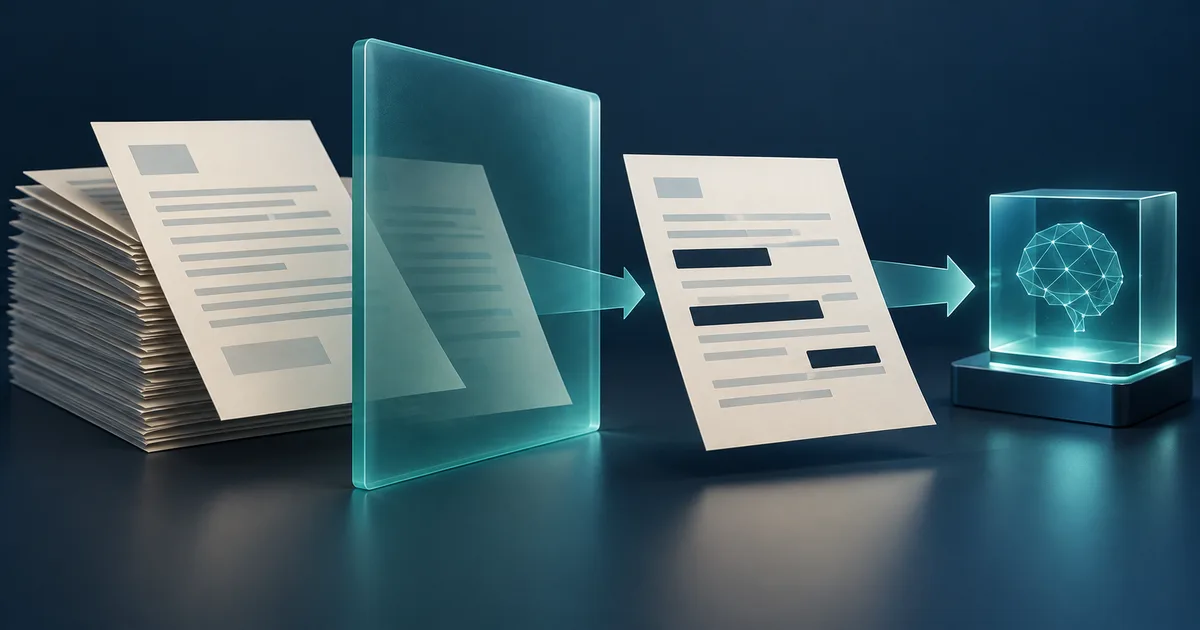
Sensitive-data redaction before AI processing means that only information necessary and authorized for the task crosses the processing boundary. A support-ticket classifier usually does not need the customer's full name or home address. Sending the entire record and asking the model to keep it confidential is not equivalent to limiting the input before transmission.
This guide concerns input preparation and outbound data controls in business software. It does not offer a guarantee of complete security or a legal compliance determination. The data type, destination and organizational permissions need separate assessment for each use case.
Define the task before designing the filter
“Read the case” is too broad. Does the model classify an issue, produce an operational summary or extract specified fields? Identify the minimum information needed for that output. Otherwise, entire records, conversation histories and attachments can be included by default.
For ticket routing, an error description and affected feature may matter while the sender's email signature does not. Conversely, removing the device model may destroy information needed for a useful classification. The objective is informed minimization, not deleting every number or proper noun.
Have the process owner identify necessary information, replaceable information and information prohibited for the destination. An internal project name may be sensitive even when a general-purpose detector does not recognize it.
Removal, masking and substitution are different
Removal excludes unnecessary material entirely. Masking replaces a value with a generic marker. Consistent substitution can preserve relationships: two references to the same person become the same placeholder within a request.
If a mapping can restore the original values, the information is not necessarily anonymous. Protect that mapping separately, limit its lifetime and do not send it alongside the substituted text. A label such as “anonymized” should not obscure the continued ability to reconnect a record to a person.
Indirect details matter too. A role, location, date and unusual event may identify someone even without a name. Generalize unnecessary detail where appropriate, while checking that the change does not invalidate the task.
Apply the control before the first external transfer
Sending raw text to an external model to identify sensitive content already moves the data across that boundary. Detection must run in an environment authorized to receive the raw input. That may be internal infrastructure or an approved service; the choice depends on the organization's policy.
Inspect the actual assembled request. Retrieved documents, conversation history, tool output, filenames and attachments may all be added beyond the visible user message. Filtering a smaller preview does not establish that the transmitted request is filtered.
Deployment location is related but separate. Our private AI deployment guide discusses that decision. Even inside private infrastructure, components should receive only the data they need and are permitted to access.
Combine detection methods with domain knowledge
Recognizable formats
Rules can identify some structured values, but context matters. A number may be a part identifier rather than a telephone number. Spaces and alternative digit forms may also affect detection. Persian-language testing should include Persian and Latin digits, mixed character forms and realistic input variations.
Context-dependent entities
Names and addresses do not always follow a fixed format. Entity recognition can help, but coverage must be tested for the language and document type in use. The Presidio Analyzer documentation describes a framework for sensitive-entity analysis. Using a ready-made framework does not demonstrate reliable coverage of your organization's Persian text.
Business-specific information
Customer organizations, internal contract references and confidential project names may need custom rules. Give those rules an owner and a review process. Record the policy version so a later investigation can establish which controls applied to a request.
Include attachments and logs in the boundary
A cleaned text prompt provides little protection if an attached screenshot still shows the same identifiers. Documents may contain headers, scanned images, hidden text layers or metadata. Verify the content of the actual outgoing file. A visible black rectangle does not necessarily remove the information beneath it.
Logs can retain raw information before filtering occurs. Prefer operational evidence such as request identifiers, policy versions and detection counts when full content is unnecessary. Any retained diagnostic samples need a separately defined purpose and restricted access.
Retention is another control, not a side effect of redaction. Our AI assistant memory retention guide covers this adjacent concern. Cleaning today's input does not authorize indefinite storage of its output or a reversible mapping.
Example: routing a service request
Consider a hypothetical message containing customer contact details and a report that a device stopped starting after an update. Routing may need the device model, symptom and relative timing, but not the person's address. Send the technical context while excluding unnecessary identifiers. The returned category does not grant access to the full customer record.
If two people or devices appear, do not replace both with an identical marker. Preserve distinctions that the task needs, using placeholders scoped to the relevant request. Check both data reduction and the usefulness of the resulting classification.
This is an illustrative scenario, not a client performance result. Start with synthetic examples and use real samples only where authorized and controlled. Test reports and screenshots should not become a new channel for publishing private information.
Decide what uncertainty should do
A detection failure must not automatically send the unfiltered input. For higher-risk material, blocking transmission and routing to an authorized review path may be appropriate. Explain that processing did not occur and provide a next step without repeating sensitive content in a public error message.
Different input types may need different policies. A structured low-risk request and an unfamiliar attachment need not share the same path. Define the paths and review permissions ahead of time rather than relying on improvised operator decisions.
Measure missed data and lost meaning
Two failure types matter: sensitive information remains, or useful context is removed unnecessarily. Evaluate both using labeled examples. Report results by data category and input type rather than relying on an unexplained overall accuracy number.
Test the final outbound request, not just the filtering function. A later step could add the original name back from conversation history. Include errors, retries and alternate processing routes. A successful ordinary request does not prove coverage of every path.
Agree acceptance criteria with the data owner and document unsupported cases. Re-run relevant tests when rules, detectors or document formats change. A new version can improve one category while performing worse on another.
Make minimization a product requirement
Define the task, select necessary data and place a testable control before transmission. Treat substitution, attachments, logging and failure behavior as parts of the same workflow. None of these measures alone eliminates all risk.
To assess a specific workflow through EasySaz AI services, begin with synthetic input, the desired output and a list of prohibited information. The useful deliverable is a data-flow map and acceptance criteria—not merely a confidentiality sentence added to the prompt.